Tencent Releases a Live Translation Model That Anyone Can Download
Tencent Hunyuan has published the weights of Hy-SimulMT, a model that interprets between spoken Chinese and English while the speaker is still talking, under the Apache 2.0 open license. The company's model card dates the release to Oct. 26, 2026.
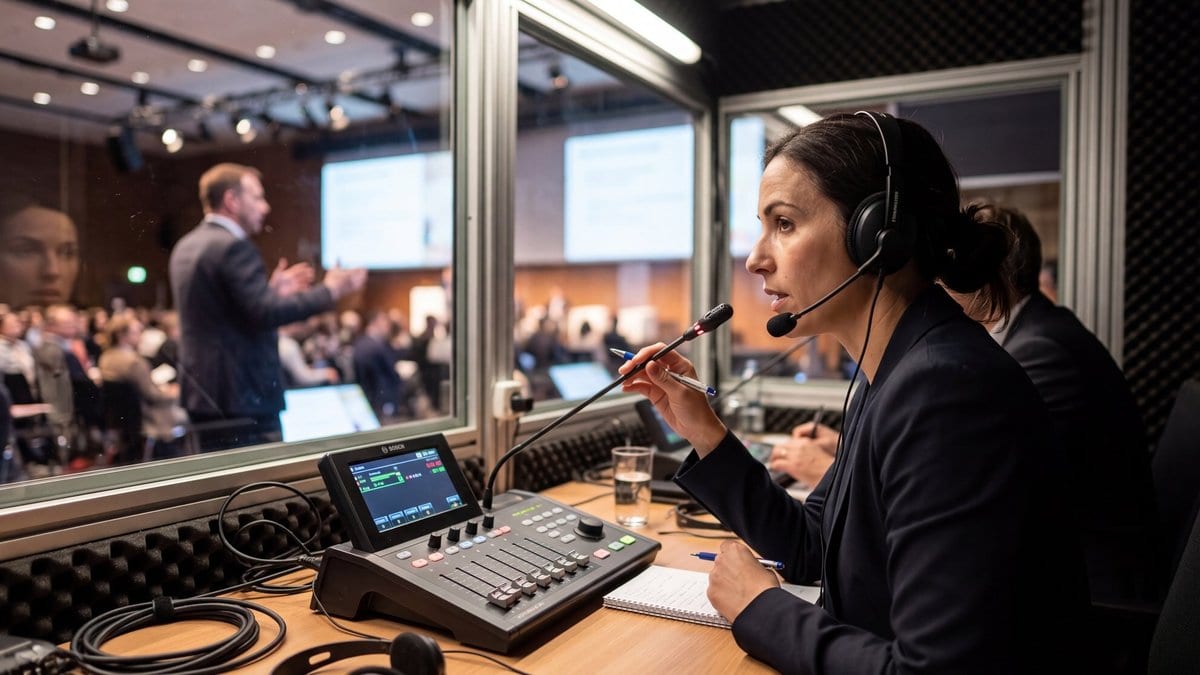
Tencent says the model is built for live meetings, speeches and interviews. It takes a continuous audio stream and produces translated text and speech as the speaker talks, rather than waiting for a sentence to finish, and a real-time voice cloning feature carries the speaker's own vocal characteristics into the translated speech. The license lets anyone download, run and modify it.
The release covers several builds, including compressed versions for smaller hardware and variants that print the source text alongside the translation. Tencent also published an inference service, SimulInfer, and a set of training tools, SimulTrain. The model card says speech output and voice cloning require a separately configured text-to-speech service.
Every performance figure for Hy-SimulMT comes from Tencent's own evaluation, and no independent evaluation of the model has been published. On the RealSI long-form audio benchmark, Tencent reports a lag of about 3 seconds on a streaming measure it calls StreamLAAL, and the card notes on the same page that this is not the same thing as the time before the model starts speaking.
Tencent describes a comparison with people. Six working interpreters holding CATTI Level 1 and Level 2 certificates interpreted 18 Chinese and English recordings collected from September 2026 onward, and the company says its model reached translation quality on a par with them while often responding faster. The card states that the finding applies only to those recordings, those interpreters and that test setting, and that it is not a comprehensive assessment of speech quality or voice similarity.
The model card points readers to a consumer app, Hy Translate, and lists copies of the model on Hugging Face and ModelScope.